Cloudflare blocked your news scraper? There's a better solution.
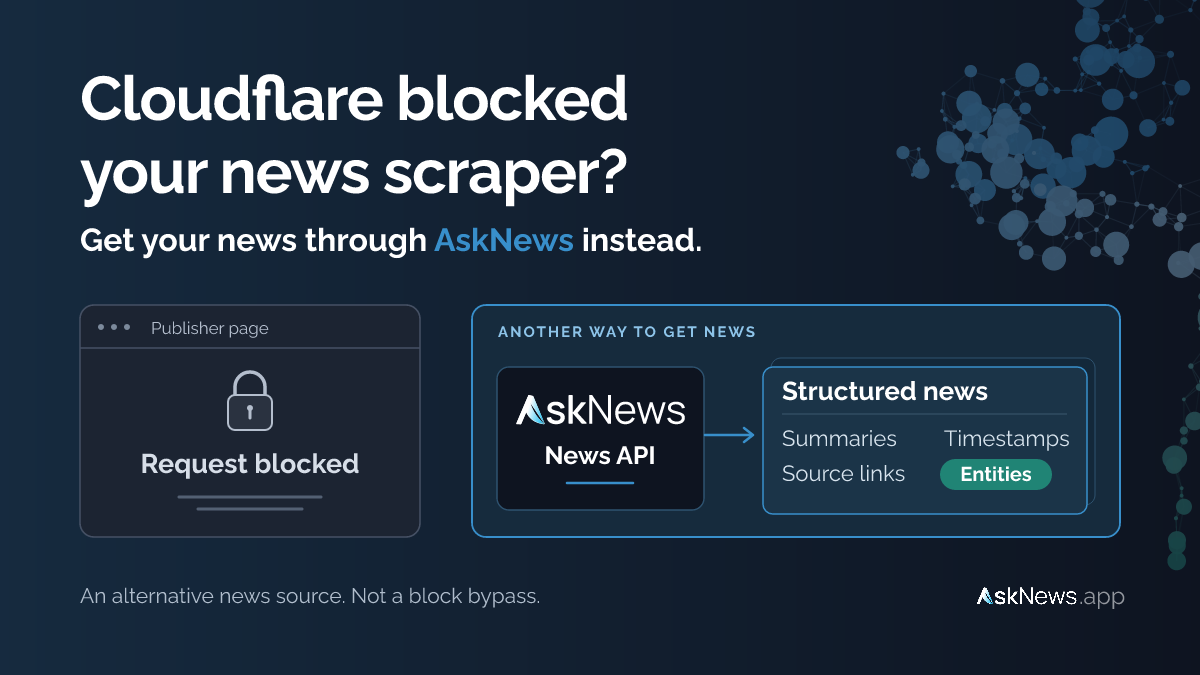
Your agent's access to news websites broke overnight thanks to Cloudflare's new policy to automatically block bots. And they have every right to block you because you violated their terms of service.
Before you spend another sprint repairing your noisy and illegal web scraper, it might be a good time to consider a more reliable, faster, legally sound, news solution.
On September 15, 2026, Cloudflare announced updated crawler controls, including a new “Disallow AI Training” setting. For new ad-supported domains, its default configuration allows Search, disallows AI training, and blocks Agents on pages with ads. Chances are, your bot is now blocked. That means your news pipeline broke overnight and the engineering decision is immediate: keep maintaining a brittle retrieval path, or evaluate news delivered through an API.
AskNews gives you a different starting point: searchable news records with summaries and source metadata, AI-ready and token-optimized for your agent.
Replace the news-retrieval step
A scraper starts with a messy HTML page. But your application needs more signal and less noise: relevant reporting, a publication time, a source link, and enough context to decide what matters. We wrote a blog focused on the rationale behind downstream token-optimization. In short: paying more up-front for clean, legal news, saves you money on tokens downstream.
Here is a news search we ran through the AskNews CLI on September 17, 2026:
asknews news search 'Cloudflare AI crawler controls and bot blocking' \
  --entity-guarantee Organization:Cloudflare \
  --hours-back 72 \
  --limit 10 \
  --return-type string \
  --output json
The example assumes the CLI is installed and authenticated with an AskNews account that has API access. It searches the preceding 72 hours and requests a maximum of five results. The optional entity filter keeps “Cloudflare” in scope.
That run returned 10 diverse and highly relevant records in 50 ms. Each included an article URL, publication timestamp, summary, entity metadata, and 20 other fields including geo-coordinates, entity relationships, bias, sentiment etc. This rich, clean response can go directly into your
|
Returned field |
Application use |
|---|---|
|
|
Keep the original source link alongside the record |
|
|
Apply a publication-time cutoff |
|
|
Supply news context to a briefing or retrieval workflow |
|
|
Inspect the people, organizations, and places identified in the reporting |
The news documentation describes keyword and semantic retrieval, time and entity filters, and structured or prompt-optimized output. The CLI makes that retrieval easy to inspect before you wire it into your application.
For an agent briefing, that means passing news context and source links into the next step. For a monitoring service, it means evaluating records against the companies, topics, and time window you care about. Your team can work on relevance and delivery instead of extracting those fields from publisher HTML.
Investigate the entities you have not identified yet
Use asknews news search for a surgical, fast lookup when you already know the entities and do not need iterative discovery. On the other hand, DeepNews attaches your agent to iterative deep research across news and other sources. DeepNews is ideal for finding and following leads, identifying unknown entities, and connecting evidence across sources.
This example asks DeepNews to investigate those unknowns rather than retrieve a fixed set of articles:
asknews research "Which industries are most affected by the conflict
in the middle east? Identify secondary and tertiary effects related
to oil supply shifts, policy reactions, and forecast how these
industries will evolve during the next 6 months" \
  --sources asknews,x,wiki,google,podcasts \
  --max-depth 50
  --output json
The source selection enables AskNews news, X, Wikipedia, Google search, and podcasts. AskNews coverage includes licensed paywalled reporting where available; source access and returned coverage depend on your account, the source, and the topic.
It's important to note that DeepNews' iterative research can take more time and cost more than a direct news search. Here, --max-depth 50 sets the maximum allowed research depth, which means it can make 50 independent retrievals across AskNews, X, Wikipedia, Google, and Podcasts. Use this deeper investigation when discovering entities and resolving open questions matters; keep the search above for targeted retrieval. This research example was syntax-checked against CLI help, not executed for this article.
Move a workflow, not your entire stack
The useful migration boundary is the point where your scraper hands an article record to the rest of your system.
Keep your queues, storage, ranking logic, and application interface. Evaluate AskNews as the input to that boundary:
- Match the reporting you need. Use real company names, topics, languages, and date ranges from your workload. Check whether the returned coverage answers your users’ questions.
- Map summaries and metadata deliberately. Preserve source links and timestamps. Check that the available fields fit the job; a summary-based briefing and an application requiring full article text have different requirements.
- Test the downstream result. Compare relevance, freshness, and missing stories before switching traffic. Keep authentication, rate-limit handling, retries, and monitoring in your integration.
The result of that evaluation is more useful than another successful page fetch: you will know whether the news your product needs can arrive as data your code already understands.
Spend engineering time on the product
Cloudflare’s September update gives site owners more precise choices about automated access. A news product built on scraping has to live with those choices, alongside changing page layouts and extraction logic.
AskNews lets you evaluate a news-data service instead. It supplies news from its own available corpus; it does not bypass Cloudflare or unlock arbitrary blocked URLs. Check coverage and permitted use against your requirements before moving a production workload.
If what you need is news context for a briefing, monitoring system, or AI application, start with the record your product needs rather than the page your scraper cannot fetch.